


JUICE: Unified Multimodal Modeling in Pretrained Representation Spaces
arXiv preprint 2026
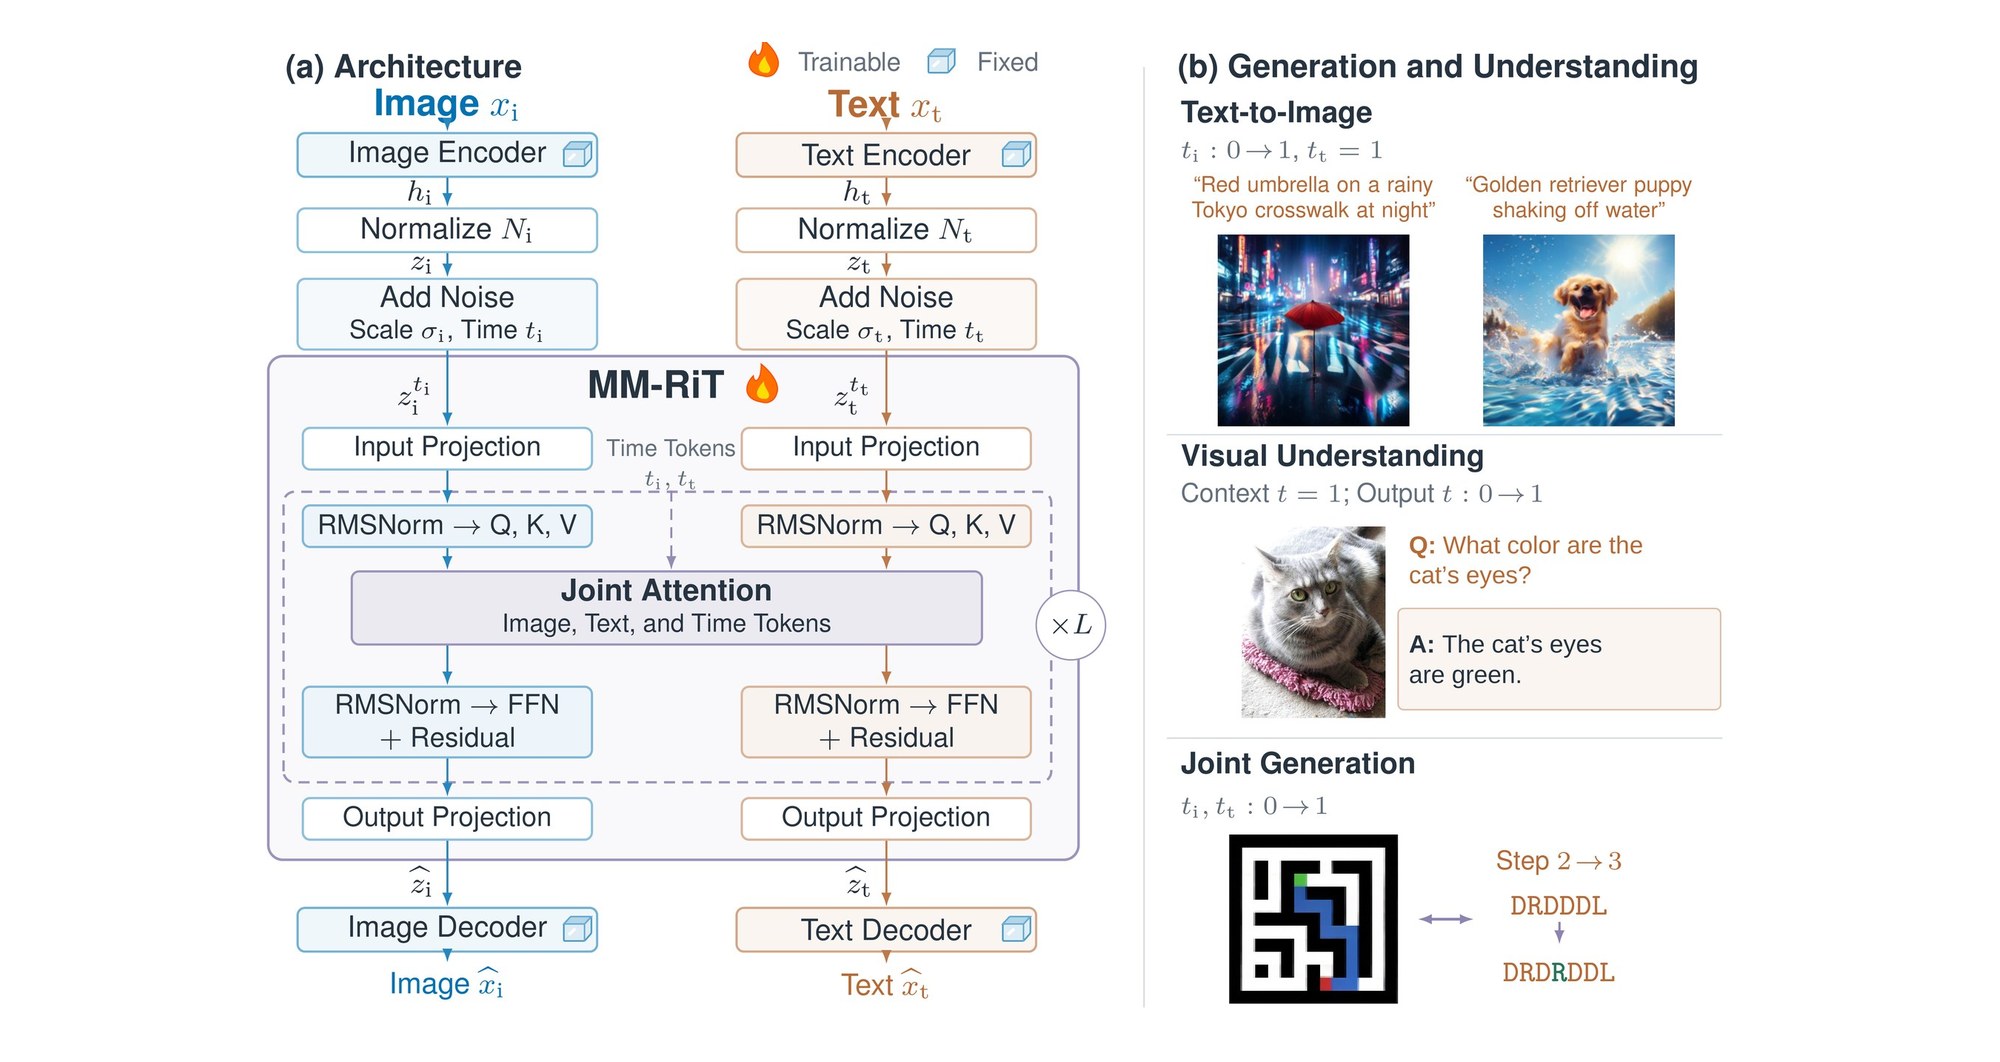
One flow matching Transformer, trained from scratch, models images and text jointly in the continuous spaces of frozen pretrained encoders. Text-to-image generation, visual understanding and joint generation become paths through one square of noise levels.